Platform
Every capability, organised by the loop it serves.
From the first prompt set to the re-measurement that proves a change. Real screens from a live tenant; no mock-ups.
Stage 1 · Configure
Three ways in. Every path lands in the same durable pipeline, so the stage survives restarts, devices and sessions.
- System Prompts
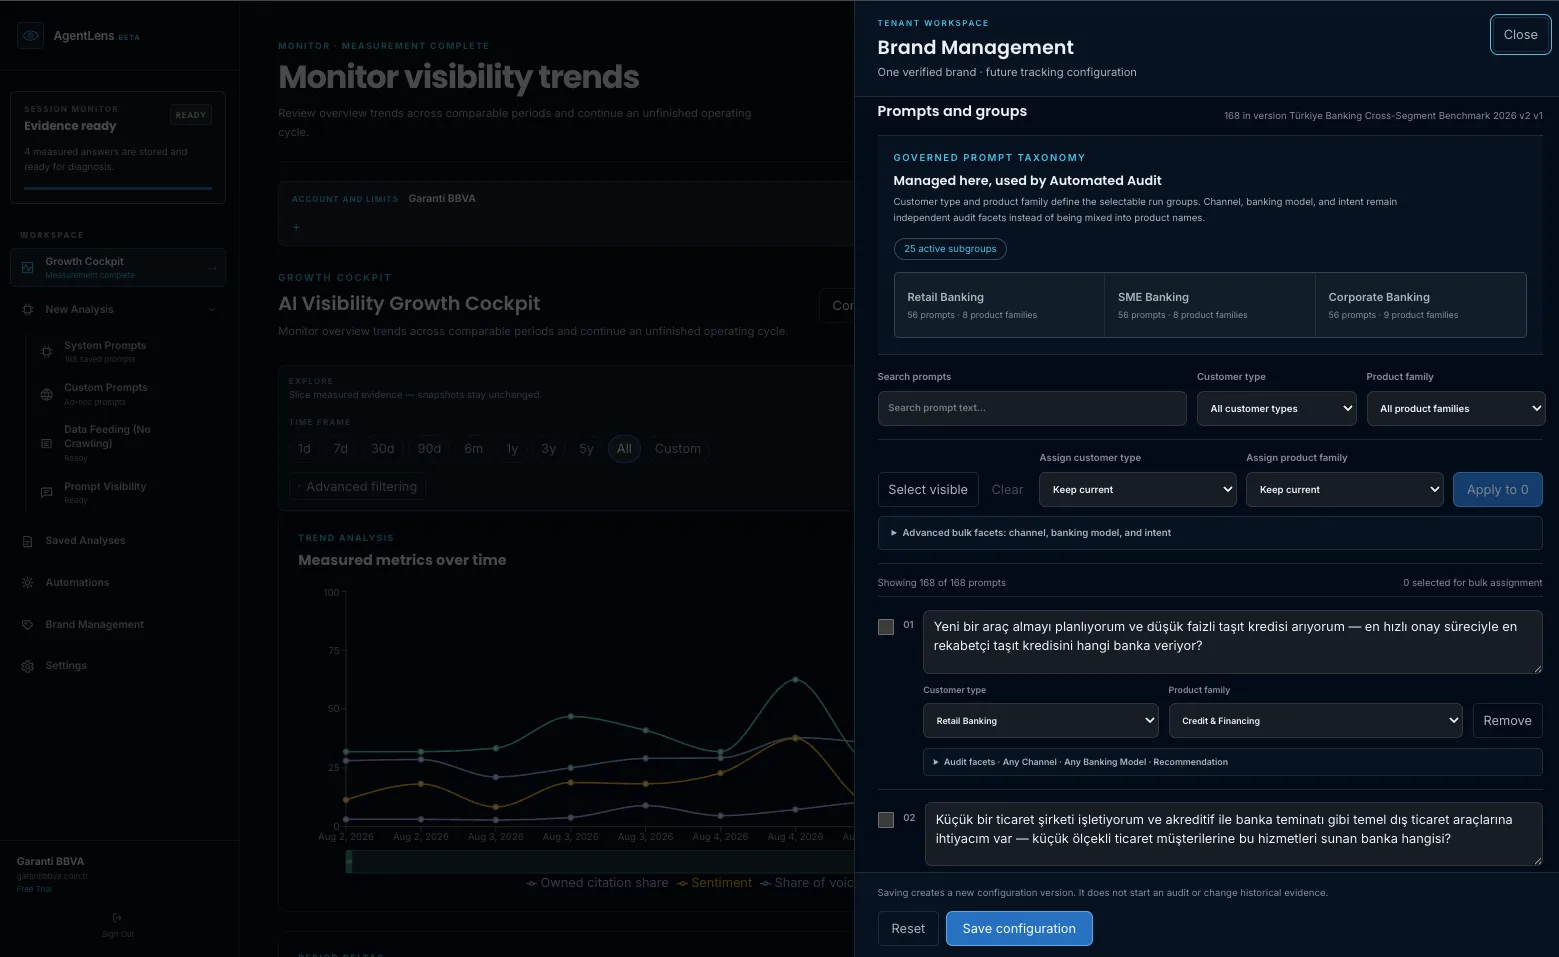
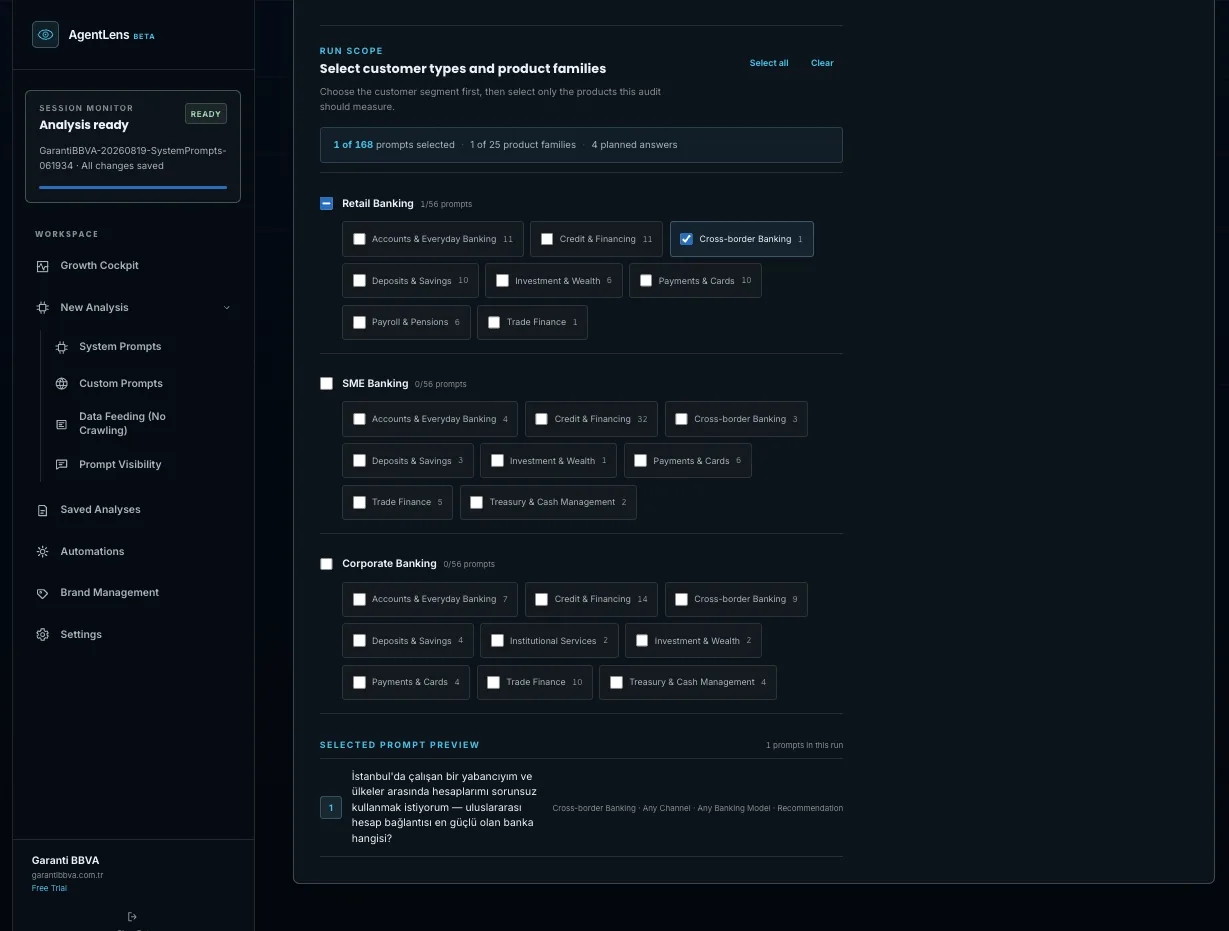
- Measure the governed prompt set saved for your sector and brand: Turkish banking ships 168 prompts across retail, SME and corporate segments.
- Custom Prompts
- Ask ad-hoc questions without touching the saved taxonomy. The right way to test a campaign or a product launch.
- Data Feeding
- Audit a product feed (CSV, JSON, XML) with no crawling at all, for sites that block crawlers or catalogs that have not shipped yet.
- Brand Management
- Version your prompts, sector rivals, AI surfaces and cadence. Saving creates a new prompt-set version and never rewrites history.
- Prompt taxonomy
- Recommendation, research and comparison intents, scoped by customer type, product family and channel, so results can be sliced later.
Stage 2 · Measure
Real vendor models, real answers, recorded per prompt and per surface. Nothing is simulated.
- Five surfaces
- ChatGPT, Claude, Gemini and Grok through their vendor APIs, plus Google AI Mode read as a live search surface.
- Estimate → confirm → run
- A spend-free estimate with pinned models, expected calls and a hard cap at 115%. A run exists only with a current, single-use estimate and your confirmation.
- Smallest detectable change
- The estimate states the least week-over-week movement the run could confirm, so you never buy a benchmark that cannot answer the question.
- Variance control
- Multi-trial averaging, pinned model versions, deterministic sampling and a 95% confidence interval on every metric.
- Bring your own keys
- Save, test, rotate and delete OpenAI, Anthropic, Gemini and xAI keys. Encrypted at rest; owners and admins only.
Stage 3 · Diagnose
Crawl-based or feed-based. Roughly 25 pages sampled, product and category pages classified automatically.
- Smart crawler
- Sitemap discovery, two-stage sampling, a 7-tier fetch cascade for WAF-protected sites and optional headless rendering for JS-heavy pages.
- Schema & content audit
- Per-page JSON-LD extraction and validation, semantic HTML scoring, meta quality and llms.txt detection.
- AI bot access check
- Detects whether GPTBot, ChatGPT-User, ClaudeBot, PerplexityBot and Googlebot are blocked in robots.txt.
- Evidence map
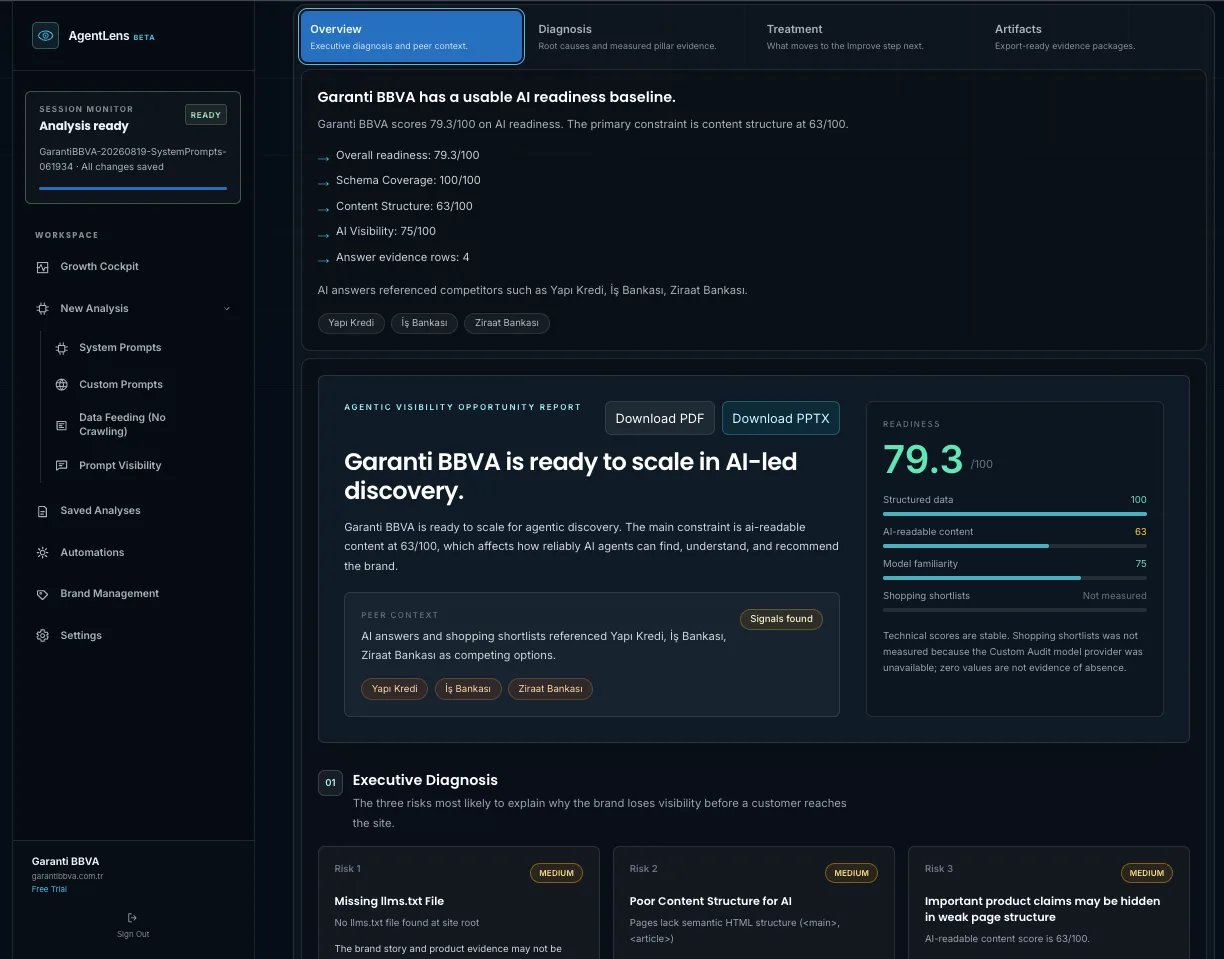
- A full causality trail from every score back to the page, tag or model answer that produced it.
- History & diff
- Audit history, snapshot comparison, added and removed page detection, per-audit token and cost tracking.
- Action queue
- Ranked, evidence-backed work items assembled from what the pipeline recorded, not a generic checklist.
Stage 4 · Improve
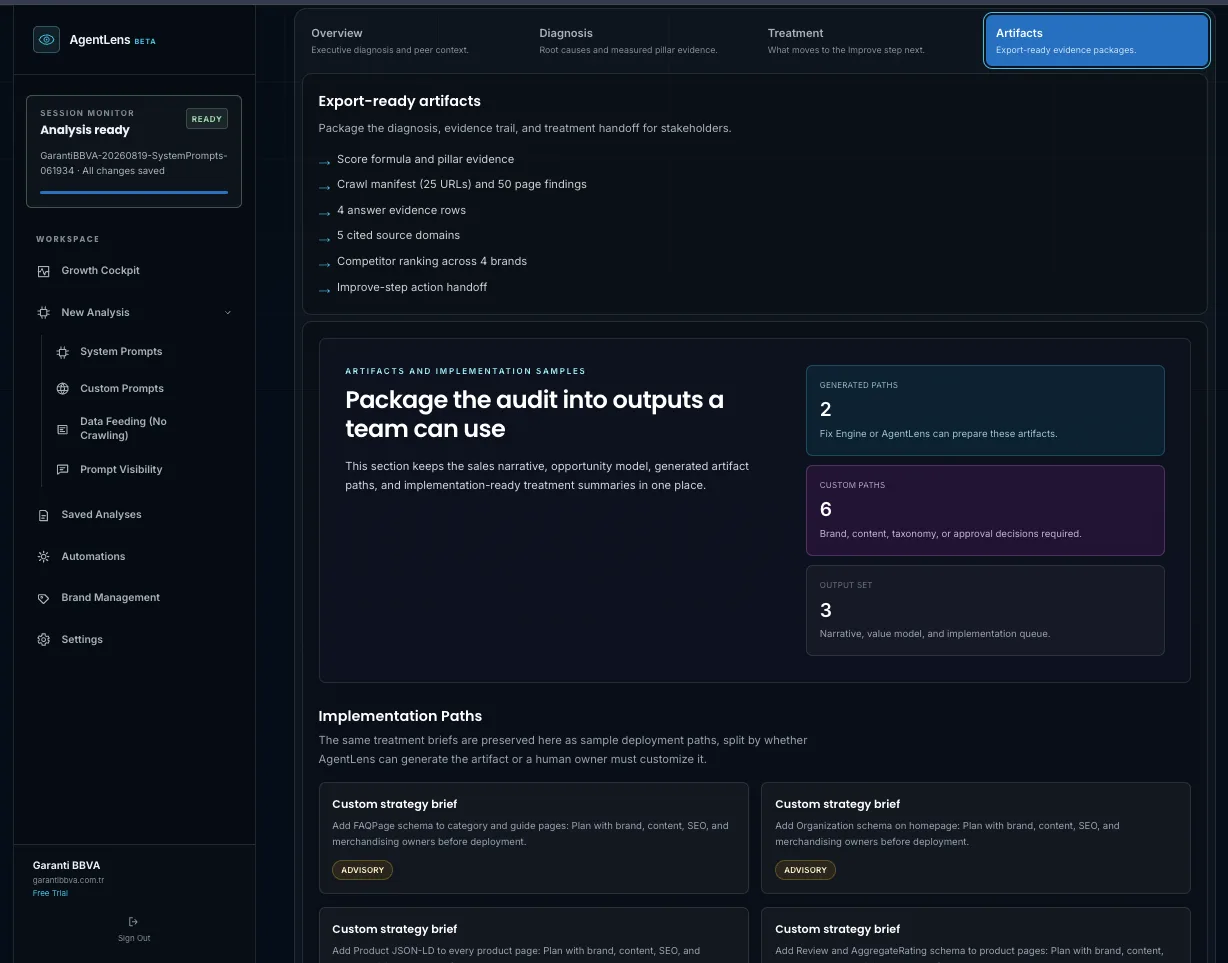
Every diagnosis produces an artifact. You review it, you deploy it. Nothing is pushed to your site by AgentLens.
- JSON-LD generator
- Complete structured-data blocks for the pages that lack them.
- llms.txt generator
- A spec-compliant file for your root, built from brand identity and the crawl manifest.
- robots.txt fixer
- Unblocks the AI crawlers you want and keeps the ones you do not.
- Meta tag optimiser
- Title, description and Open Graph tags rewritten for the page.
- Semantic HTML audit
- Pattern detection plus fix snippets for the markup agents read.
- Fact-Feel-Proof rewriter
- Three-block product descriptions written for model comprehension.
- Doc2Query++
- Synthetic queries plus FAQPage JSON-LD, so the page answers the questions people ask assistants.
- Image audit & attributes
- Missing-alt detection with AI captioning, and inferred attributes enriched into your JSON-LD.
LLM-assisted drafting runs on your own provider key or the platform model plane. Measurement never does.
Stage 5 · Integrate
Generated and validated packages for the three emerging agentic-commerce standards. Registration, upload and merchant approval stay with you.
Input
Your crawled catalog
Product pages, attributes, relationships and prices as the audit recorded them.
Also generated
- Relationship tagger: substitute, accessory, cross-brand
- Agent-first API: OpenAPI spec + FastAPI sample
OpenAI
ACP
Agentic Commerce Protocol
ACP-compliant JSON + TSV product feeds, validated.
Google
UCP
Universal Commerce Protocol
Merchant Center JSON + XML with conversational attributes.
Anthropic
MCP
Model Context Protocol
Docker-ready Python MCP server, scaffolded and downloadable.
- ACP · OpenAI
- ACP-compliant JSON and TSV product feeds with validation.
- UCP · Google
- Merchant Center JSON and XML with conversational attributes.
- MCP · Anthropic
- A Docker-ready Python MCP server, scaffolded and downloadable.
- Relationship tagger
- Substitute, accessory and cross-brand relationships across your catalog.
- Agent-first API
- An OpenAPI spec plus a FastAPI sample you host, so agents can query your catalog directly.
Stage 6 · Govern
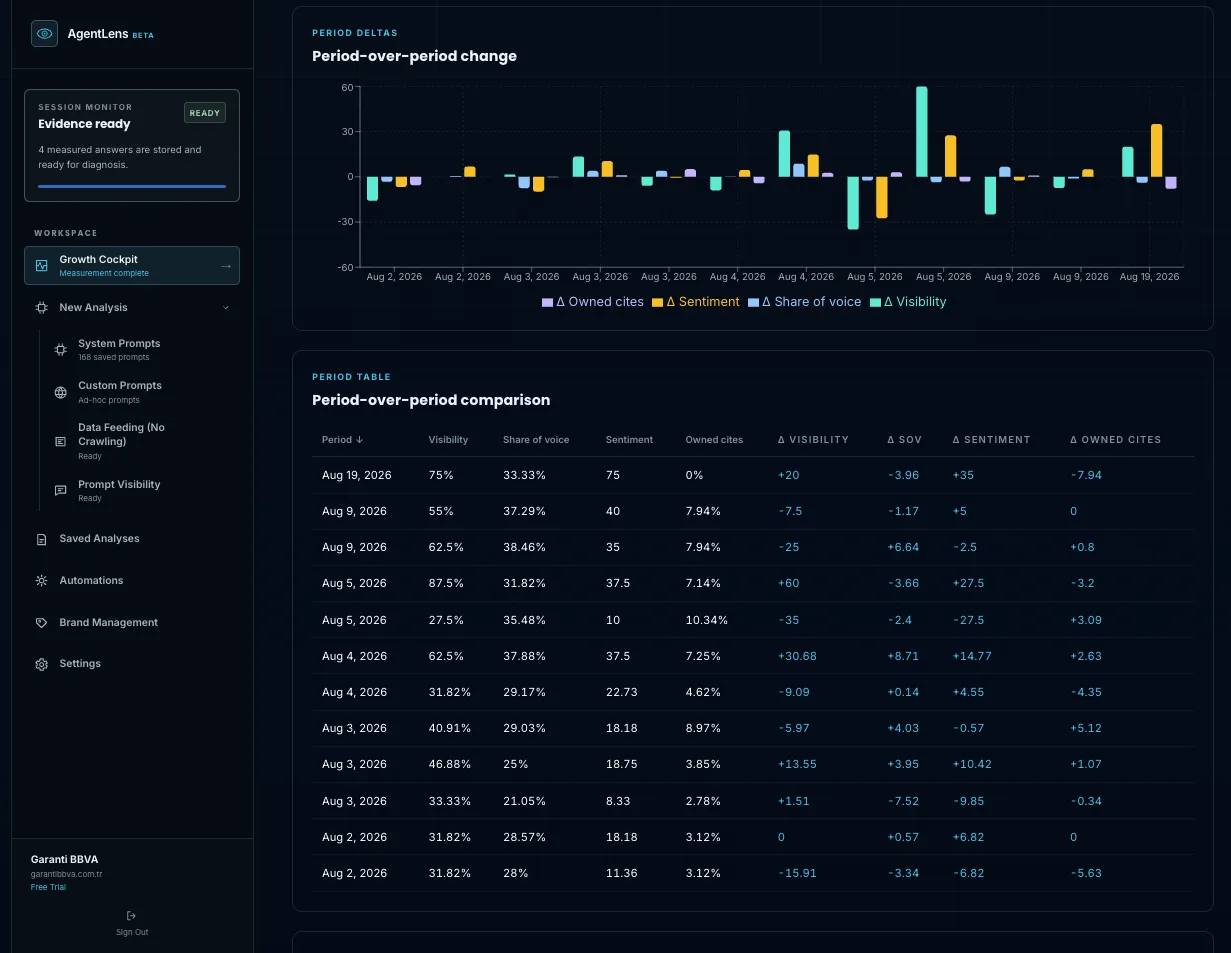
Visibility is a moving target. Automations keep measuring after the fixes ship and only raise an alarm when a movement is bigger than sampling noise.
- Automations
- Scheduled re-measurement delivered to Slack, Microsoft Teams, email or a webhook, with an alert inbox. Each cycle runs under its own hard cap; one that would exceed it is refused.
- Alerts that survive a significance test
- A week-over-week drop reaches high severity only when a two-proportion test rejects noise at α 0.05. A real drop names its metric in the subject line.
- Sources to earn
- Cited sources that informed answers naming a rival but not you: a ranked, exportable list of places to get listed.
- Benchmark exploration
- Slice visibility and comparison results by scope, topic, intent, provider and active rival pool. Dashboard and report filters agree.
- Exposure ledger & snapshots
- Portfolio trends, per-brand breakdown, weakest and strongest pillar; immutable report snapshots as PDF, PPTX, XLSX and JSON.
- Sector catalogs
- Turkish banking (47 banks, tiered rival pools) and fashion (99 tagged brands) today. Fintech, tech & electronics and lodging as approved packs.
See it on your own domain
One confirmed run. One evidenced report.
Give us your domain and at least three questions your customers ask. We reply within five business days.