Agentic Visibility Platform · Beta
Know what the agents say about you.
Your customers now ask an assistant before they ask a search box. AgentLens measures whether ChatGPT, Claude, Gemini, Grok and Google AI Mode find, read and recommend your brand, turns the evidence into fixes you approve, and re-measures to prove the change.
- Measured across
- ChatGPT
- Claude
- Gemini
- Grok
- Google AI Mode
Discovery is moving to agents
Rankings tell you where you sit on a results page. They say nothing about whether a model recommends you.
Assistants now sit between your brand and the buyer, reading your site, your feed and their own model priors before a human ever sees a shortlist. In Türkiye, Google AI Mode has been live since February 2026.
A customer asks
“Which bank has the best travel credit card in Türkiye?”
Not a keyword. A question, in the customer’s own words, to an assistant that will answer with names.
What the answer says
Live search · Google AI Mode- #1Rival bankRecommended
- #3Your brandAlso consider
- —Another rivalNeutral
Evidence“…for frequent flyers the miles card from [rival] is the strongest pick; [your brand]’s card is also worth a look…”
Illustrative answer. AgentLens classifies only where a verbatim quote names the brand; otherwise the judgement is discarded, not guessed.
Traditional SEO metrics no longer answer
- Does AI recommend my brand when buyers ask?
- Is my site structured for agent consumption?
- Where do I land in AI shopping shortlists?
- Which fixes can I deploy right now?
- Are my products reachable over ACP, UCP and MCP?
The shift, in numbers
AI-mediated discovery is already a measured channel.
AI-referred shoppers are still fewer than search shoppers, but they arrive decided: +53% revenue per visit (Adobe) and nine times the conversion of social referrals (Salesforce).
- $3–5T
- global agentic-commerce revenue by 2030McKinsey, Oct 2025
- $15T
- of B2B purchases intermediated by AI agents by 2028Gartner, Nov 2025
- 20%
- of 2026 holiday e-commerce traffic from AI chat agentsSalesforce, Jul 2026
- −25%
- traditional search-engine volume by 2026Gartner, Feb 2024
- 900Mweekly ChatGPT usersOpenAI, Feb 2026 · 50M paying subscribers
- 1B+monthly Google AI Mode usersAlphabet Q2 2026 earnings call, Jul 2026
- $262BAI-influenced online holiday salesSalesforce · ≈20% of $1.3T global, Nov–Dec 2025
- +54%conversion rate of AI-referred retail visitors vs other trafficAdobe Digital Insights, US retail, May 2026
One scorecard, four pillars
Transparent formulas, not a black box.
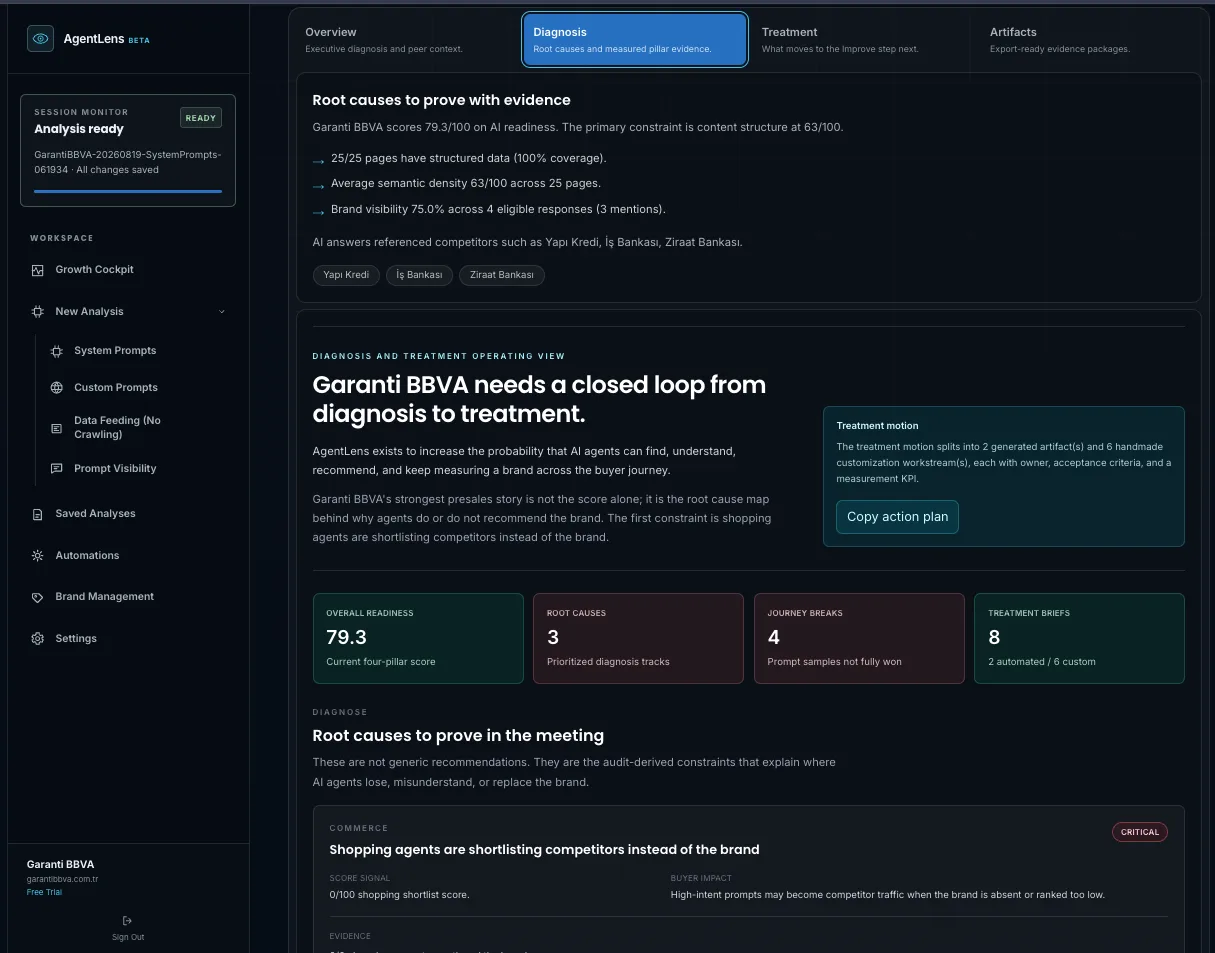
Every score traces back to source evidence: the page, the tag or the model answer that produced it.
- 25%
Schema Coverage
JSON-LD structured data: presence, correctness, completeness.
- 25%
Content Structure
Semantic HTML, meta quality, heading hierarchy, llms.txt.
- 25%
Agentic Brand Familiarness
How often AI mentions your brand organically: Share of Model.
- 25%
Shopping Assistant
Position and frequency in AI product-recommendation shortlists.
Each pillar is scored 0–100 with a 95% confidence interval. Read the formulas.
One operating loop, six stages
Every analysis moves through the same durable pipeline.
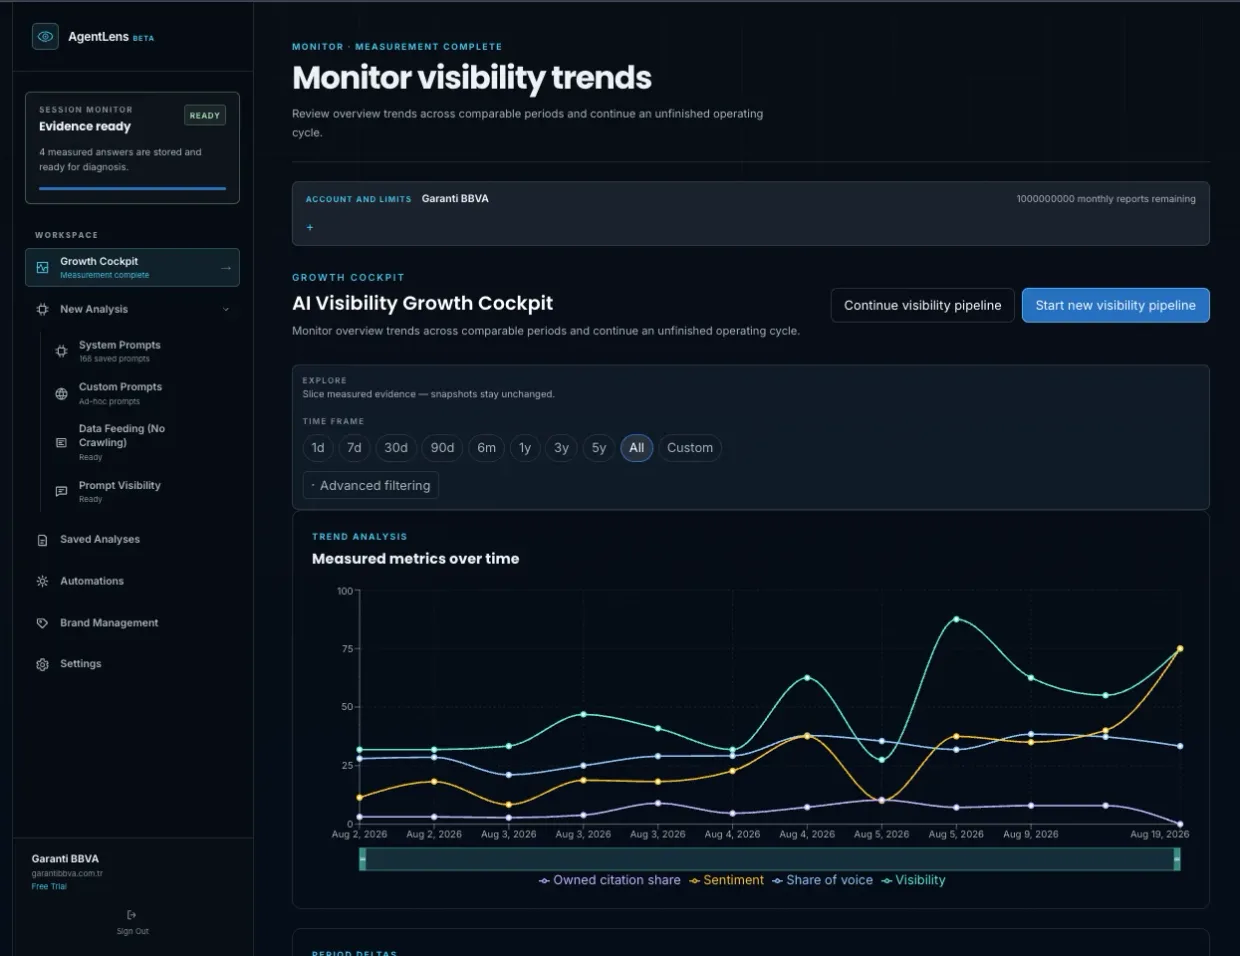
The stage is derived server-side from durable records, so it survives restarts, devices and sessions. AgentLens turns evidence-backed diagnoses into reviewable remediation and commerce artifacts, then measures what changed.
Beyond presence
Being mentioned is not being recommended.
AgentLens keeps the two apart, and only classifies where verbatim evidence exists. Historical runs stay explicitly unclassified; metric versions are pinned so dashboards never silently change meaning.
Mention quality
mention-quality-v1Role, rank (1–100) and sentiment for every judged answer. Evidence must be a verbatim quote that names the brand; otherwise the judgement is discarded, not guessed.
Product comparison quality
comparison-quality-v1When a model compares you against a rival: who was preferred, which factors drove it, and whether the cited evidence supports the outcome. Target preferred · competitor preferred · conditional · mixed · no clear winner.
Surface provenance
per answerEvery answer records where it came from: model memory with no browsing, or a live-search surface such as Google AI Mode. Grounded and ungrounded answers are shown as a split, never blended into one average.
Rivals observed
from evidenceRivals the models compared you against, but you are not tracking yet, surface with their evidence. The rival pool grows from observation, not guesswork.
What AgentLens does not do
AgentLens generates. You deploy.
Stated plainly, because the boundary is the product. A platform that tells you what it cannot do is a platform you can check.
- 01
No silent changes to your site
AgentLens never deploys to your CMS, storefront, robots.txt, DNS or merchant account. It generates; you apply.
- 02
No guaranteed rankings or sales lift
Scores and projections are decision support. Model behaviour changes; we show confidence intervals and significance, not promises.
- 03
No transactions
No checkout, no payment, no autonomous purchasing on your behalf.
- 04
No surfaces we cannot measure
If there is no real adapter for an AI surface, it is not offered or advertised. Perplexity is not on the list today for exactly that reason.
Sector benchmarks
Measured against the brands your customers actually name.
Governed prompt sets and rival pools per sector, so a result is a position in a market, not a number in a vacuum.
47
Banking & Finance
tiered rival pools · 168 governed prompts · retail, SME, corporate
99
Fashion & Apparel
tagged brands · six customer-need groups · 198-prompt benchmark next
Fintech & payments, tech & electronics and lodging & travel run as approved configuration packs over the same contracts. See the roadmap.
Start with one analysis
Demand your agentic visibility report.
Give us your domain and at least three questions your customers ask. One confirmed run returns a four-pillar score with its evidence, mention quality per answer and a prioritised action queue.